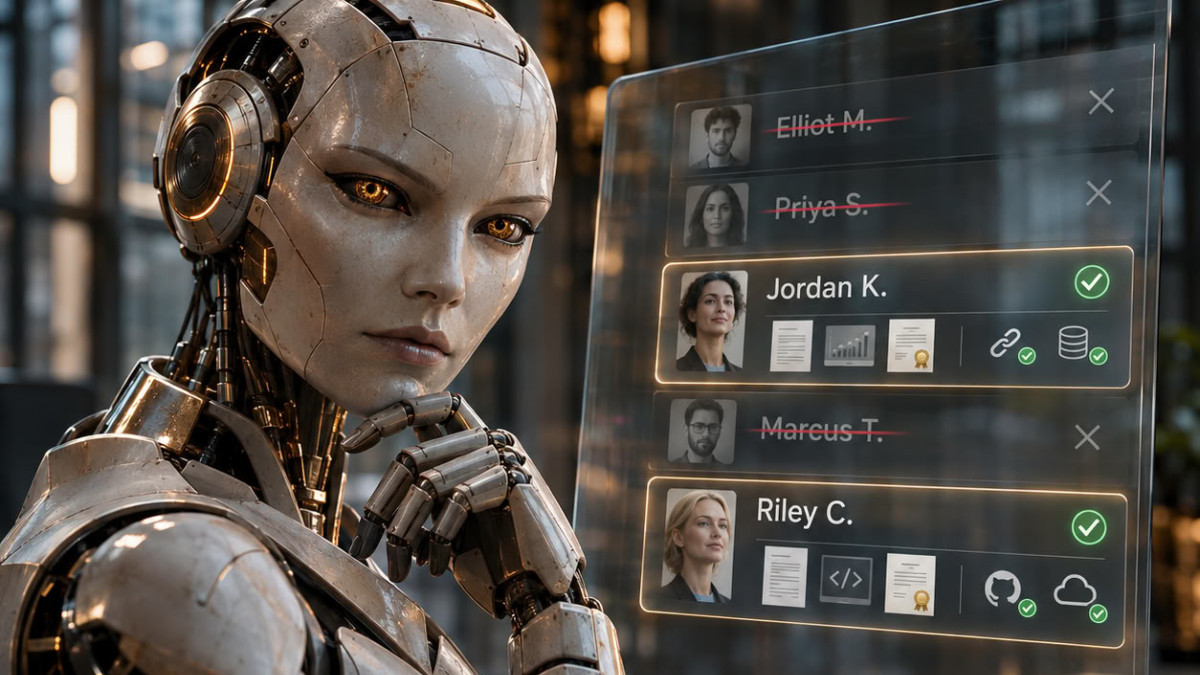

Being cited by artificial intelligences is not enough to keep your place in a buyer’s shortlist. According to a GEO (Generative Engine Optimization) consultant, a company with very strong presence in AI responses was nonetheless seeing its prospect pipeline shrink. The study he reports on addresses this apparent contradiction.
The consultant built 38 detailed, criteria-based queries, covering multiple product categories and buyer segments. These queries were evaluated across five AI interfaces, resulting in 190 responses. They mirrored the criteria a buyer uses to narrow a supplier list: fit with workflows, integrations, regulatory requirements, interoperability, or analytics. According to the author, some queries turned out to be even longer after exchanges with procurement managers.
Visibility results were high. The company was mentioned in 98.4% of the evaluated responses and featured as a primary recommendation or in a shortlist in 93.2% of cases. Yet, when these same responses were checked against decision criteria, 73.7% of them contained weak or absent evidence supporting key claims. In 15.8% of cases, a gap described as “significant” or “critical” was identified.
Visibility that is not enough to decide
For the author, there is a clear difference between asking which suppliers operate in a market and asking which ones can meet a specific combination of technical, operational, regulatory, and commercial requirements. A model may know a company and place it in a shortlist without having the necessary information as soon as the buyer asks about how an integration works or a product’s limits. These questions, he argues, are not about simple keywords but about evidence requirements.
The figures therefore do not contradict each other: they measure two different stages of the decision process. Visibility gets the company into the discussion, while the ability to decide determines if the AI has enough elements to keep it there.
Proof rather than capabilities
According to the study, a weakness in evidence does not necessarily mean the company lacks the capability in question. In many cases, it seemed to exist, but the available information did not explain it sufficiently to meet the AI’s confidence level. A promise of an end-to-end process, for example, is not supported if the process, connections, or data flows are not described. Information can also be fragmented, forcing the model to link several pages before reaching a conclusion.
The author notes that internal, original product documentation can constitute the best proof that a feature exists. Conversely, claims of superiority, efficiency, adoption, or measurable results benefit from being corroborated by customers, analysts, or independent third parties. He adds that the generalization of similar content, which he calls “content parity,” can get a company into the category without allowing it to withstand a thorough evaluation.
He finally warns against the temptation to produce “evidence-shaped” content: longer pages, superficial diagrams, weak surveys, or AI-generated case studies. The goal, he argues, is to provide real information that reduces buyer uncertainty. If a piece of information would not help an informed customer make a better decision, it should not exist solely to improve a GEO score.
Measuring the buyer all the way through
The consultant believes that measuring only an AI’s first response is insufficient. “Frequently asked questions”-type queries are useful for establishing a list of options, but current tools do not track the sequence of questions a user asks successively. He calls this multivariate combination resulting from these successive exchanges “prompt math.” He argues that GEO measurement must integrate both visibility and decision-making capability.
