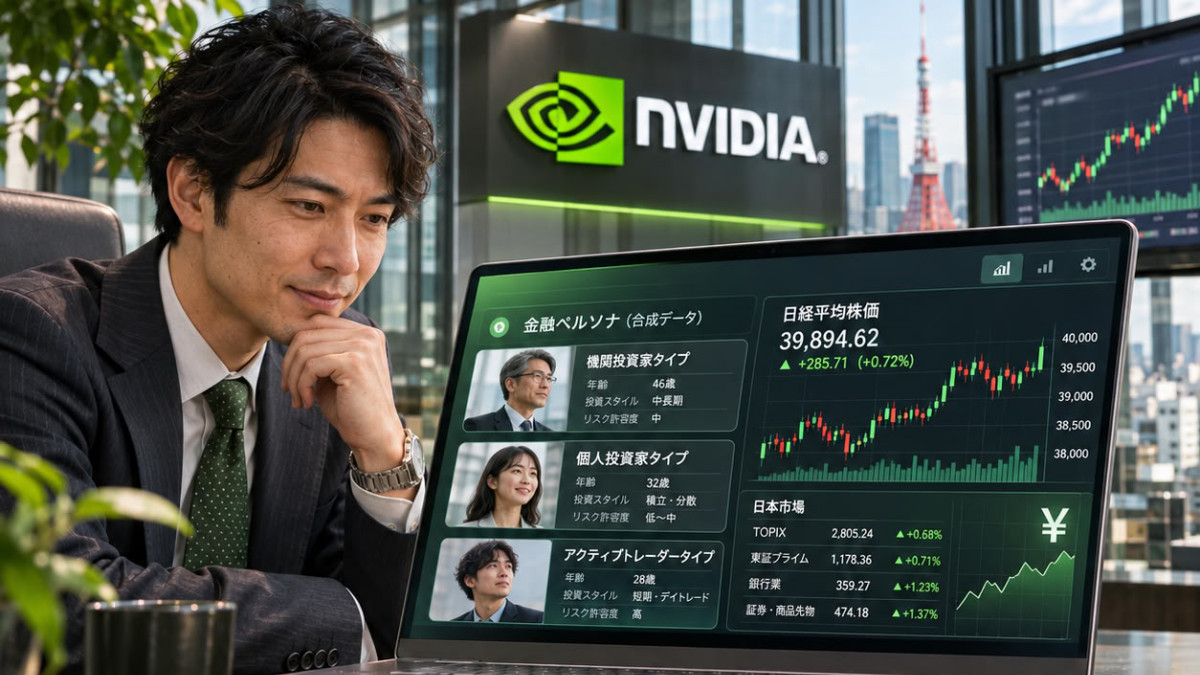

Elith and NVIDIA have released Nemotron-Personas-Finance-Japan, a synthetic personas dataset intended for developing artificial intelligence in the Japanese financial sector. A financial extension of the Nemotron-Personas-Japan dataset, it combines Japan’s official statistics with data on household finances and financial literacy. It is released under the CC BY 4.0 license, which permits commercial use.
- Elith et NVIDIA publient Nemotron-Personas-Finance-Japan, un jeu de données synthétique sous licence CC BY 4.0.
- Il combine statistiques officielles japonaises et données sur les finances des ménages et la culture financière.
- Il contient 9 millions de personas, avec environ 1,5 milliard de tokens.
- Il est destiné aux banques, assureurs et startups pour développer des agents IA sans utiliser de données clients.
In finance, the use of real data faces strict privacy rules, compliance requirements, and the need for deep domain expertise. The development of agentic AI in this field, meaning systems capable of autonomously chaining actions, requires, according to the source, synthetic data that avoids the risks associated with real data while reflecting demographics, household composition, and household assets.
The dataset was built from official government statistics, using two NVIDIA tools: NeMo SDG-PGMs, a probabilistic modeling framework for synthetic data generation, and NeMo Data Designer, a synthetic data generation system for enterprises. The gemma-4-31B-it model, distributed under the Apache-2.0 license, was used to generate the Japanese text. To make the dataset more useful for financial use cases, its design incorporated feedback from several players: Sompo Japan, Tokio Marine Holdings, Bank of Fukuoka, Mizuho Financial Group, Meiji Yasuda Life Insurance, and the Financial Data Utilization Association (FDUA).
A Large-Scale Dataset
The dataset contains 1 million records, each with 9 personas, totaling 9 million personas, written in natural Japanese. Each record contains 50 fields: 9 persona fields, 11 persona attributes, and 30 contextual fields from demographic and employment statistics. The volume reaches approximately 1.5 billion tokens, meaning text units processed by models, with about 750 million for the personas.
The personas cover several dimensions: demographics, region, asset allocation, and personality traits. They include approximately 950,000 unique names and over 1,600 occupation categories reflecting the Japanese workforce. Their attributes describe, among other things, cultural background, skills, career goals, hobbies, family and financial context, relationship with money, and financial planning.
To better reflect life situations rarely visible in statistics, the designers refined certain categories. Education level is described in more detail, new professions such as business owners have been added, and life stages such as students, retirees, or periods of unemployment have been modeled. Household finances include real assets, and internet and smartphone usage is taken into account.
Privacy and Uses
Each persona is entirely synthetic and does not represent any real person. Demographic and financial data follow official statistics and public surveys, while names respect real Japanese naming patterns. According to the source, the dataset is designed to reduce the risk of privacy infringement and does not require any customer data to be used.
Banks, insurers, and the startups that support them are the primary intended recipients. Teams can use it to create customer service agents, evaluate business processes and marketing campaigns, conduct user simulations with NeMo User Sim, or subject customer-facing AI to safety tests. The dataset can also be used to generate multi-turn dialogues, fine-tune models with culturally anchored data, and verify whether an AI’s performance remains consistent across rural and urban areas, age groups, and education levels.
On the same day, NVIDIA released Nemotron-PII-Japan, which contains 100,000 synthetic Japanese business documents with annotated personal information, intended for training and testing detection and redaction models. Its documents are based on Nemotron-Personas-Japan. The dataset is loaded using the load_dataset function from the datasets library.
